# CSV to Elasticsearch Dataflow Template
The [CsvToElasticsearch](src/main/java/com/google/cloud/teleport/v2/templates/CsvToElasticsearch.java) pipeline ingests
data from one or more CSV files in Google Cloud Storage into Elasticsearch. The template creates the schema for the
JSON document using one of the following:
1. Javascript UDF (if provided)
2. JSON schema (if provided)
3. CSV headers* (default)
If either a UDF or JSON schema is provided then it will be used instead of the CSV headers.
\*NOTE: All values will be written to Elasticsearch as strings if headers are used.
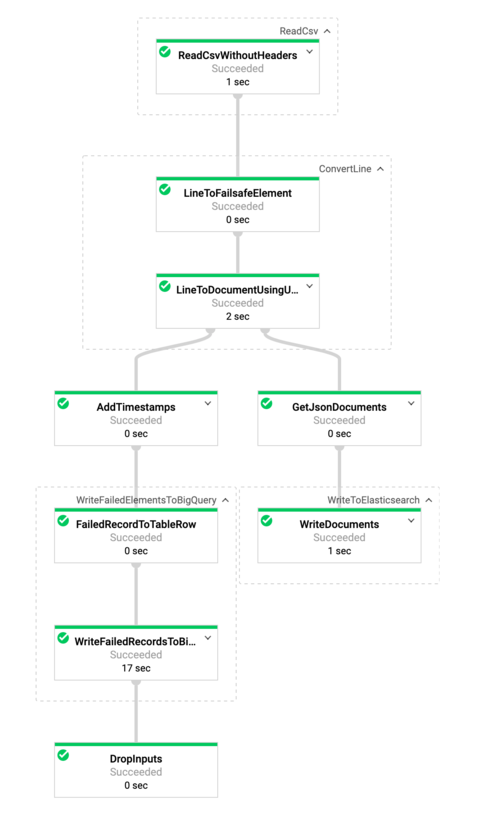
Pipeline flow is illustrated below:
## Getting Started
### Requirements
* Java 8
* Maven
* Cloud Storage bucket exists
* Elasticsearch nodes are reachable from the Dataflow workers
* Csv schema is the same for all Csvs.
### Building Template
This is a Flex Template meaning that the pipeline code will be containerized and the container will be
run on Dataflow.
#### Building Container Image
* Set environment variables that will be used in the build process.
```sh
export PROJECT=
export IMAGE_NAME=
export BUCKET_NAME=gs://
export TARGET_GCR_IMAGE=gcr.io/${PROJECT}/${IMAGE_NAME}
export BASE_CONTAINER_IMAGE=gcr.io/dataflow-templates-base/java8-template-launcher-base
export BASE_CONTAINER_IMAGE_VERSION=latest
export TEMPLATE_MODULE=csv-to-elasticsearch
export APP_ROOT=/template/${TEMPLATE_MODULE}
export COMMAND_SPEC=${APP_ROOT}/resources/${TEMPLATE_MODULE}-command-spec.json
export TEMPLATE_IMAGE_SPEC=${BUCKET_NAME}/images/${TEMPLATE_MODULE}-image-spec.json
export INPUT_FILE_SPEC=
export NODE_ADDRESSES=
export INDEX=
export DOCUMENT_TYPE=
export HEADERS=false
export DEADLETTER_TABLE=
export DELIMITER=","
gcloud config set project ${PROJECT}
```
* Build and push image to Google Container Repository
```sh
mvn clean package \
-Dimage=${TARGET_GCR_IMAGE} \
-Dbase-container-image=${BASE_CONTAINER_IMAGE} \
-Dbase-container-image.version=${BASE_CONTAINER_IMAGE_VERSION} \
-Dapp-root=${APP_ROOT} \
-Dcommand-spec=${COMMAND_SPEC} \
-am -pl ${TEMPLATE_MODULE}
```
#### Creating Image Spec
Create file in Cloud Storage with path to container image in Google Container Repository.
```sh
echo '{
"image":"'${TARGET_GCR_IMAGE}'",
"metadata":{"name":"Replicates from a CSV file into Elasticsearch",
"description":"CSV to Elasticsearch",
"parameters":[
{
"name":"inputFileSpec",
"label":"Pattern to where data lives",
"helpText":"Pattern to where data lives, ex: gs://mybucket/somepath/*.csv",
"paramType":"TEXT",
"isOptional":false
},
{
"name":"nodeAddresses",
"label":"Comma separated list of Elasticsearch nodes to connect to",
"helpText":"Comma separated list of Elasticsearch nodes to connect to, ex: http://my-node1,http://my-node2",
"paramType":"TEXT",
"isOptional":false
},
{
"name":"index",
"label":"The index toward which the requests will be issued",
"helpText":"The index toward which the requests will be issued, ex: my-index",
"paramType":"TEXT",
"isOptional":false
},
{
"name":"documentType",
"label":"The document type toward which the requests will be issued",
"helpText":"The document type toward which the requests will be issued, ex: my-document-type",
"paramType":"TEXT",
"isOptional":false
},
{
"name":"containsHeaders",
"label":"Set to true if file(s) contain headers",
"helpText":"Set to true if file(s) contain headers.",
"paramType":"TEXT",
"isOptional":false
},
{
"name":"deadletterTable",
"label":"Deadletter table in BigQuery for failed inserts",
"helpText":"Deadletter table in BigQuery for failed inserts in form: project-id:dataset.table",
"paramType":"TEXT",
"isOptional":false
},
{
"name":"delimiter",
"label":"Delimiting character in CSV file(s)",
"helpText":"Delimiting character in CSV file(s). Default: use delimiter found in csvFormat",
"paramType":"TEXT",
"isOptional":false
},
{
"name":"csvFormat",
"label":"Csv format according to [Apache Commons CSV format](https",
"helpText":"Csv format according to [Apache Commons CSV format](https://commons.apache.org/proper/commons-csv/apidocs/org/apache/commons/csv/CSVFormat.html). Default is: Default.
NOTE: Must match format names exactly found [here](http://commons.apache.org/proper/commons-csv/apidocs/org/apache/commons/csv/CSVFormat.Predefined.html#Default)",
"paramType":"TEXT",
"isOptional":true
},
{
"name":"jsonSchemaPath",
"label":"Path to JSON schema",
"helpText":"Path to JSON schema, ex gs://path/to/schema. Default: null.",
"paramType":"TEXT",
"isOptional":true
},
{
"name":"largeNumFiles",
"label":"Set to true if number of files is in the tens of thousands",
"helpText":"Set to true if number of files is in the tens of thousands. Default: false",
"paramType":"TEXT",
"isOptional":true
},
{
"name":"batchSize",
"label":"Batch size in number of documents",
"helpText":"Batch size in number of documents. Default: 1000",
"paramType":"TEXT",
"isOptional":true
},
{
"name":"batchSizeBytes",
"label":"Batch size in number of bytes",
"helpText":"Batch size in number of bytes. Default: 5242880 (5mb)",
"paramType":"TEXT",
"isOptional":true
},
{
"name":"javascriptTextTransformGcsPath",
"label":"Gcs path to javascript udf source",
"helpText":"Gcs path to javascript udf source. Udf will be preferred option for transformation if supplied. Default: null",
"paramType":"TEXT",
"isOptional":true
},
{
"name":"javascriptTextTransformFunctionName",
"label":"UDF Javascript Function Name",
"helpText":"UDF Javascript Function Name. Default: null",
"paramType":"TEXT",
"isOptional":true
},
{
"name":"maxRetryAttempts",
"label":"Max retry attempts",
"helpText":"Max retry attempts, must be > 0. Default: no retries",
"paramType":"TEXT",
"isOptional":true
},
{
"name":"maxRetryDuration",
"label":"Max retry duration in milliseconds",
"helpText":"Max retry duration in milliseconds, must be > 0. Default: no retries",
"paramType":"TEXT",
"isOptional":true
},
{
"name":"usePartialUpdates",
"label":"Set to true to issue partial updates",
"helpText":"Set to true to issue partial updates. Default: false",
"paramType":"TEXT",
"isOptional":true
},
{
"name":"idFnPath",
"label":"Path to javascript file containing function to extract Id from document",
"helpText":"Path to javascript file containing function to extract Id from document, ex: gs://path/to/idFn.js. Default: null",
"paramType":"TEXT",
"isOptional":true
},
{
"name":"idFnName",
"label":"Name of javascript function to extract Id from document",
"helpText":"Name of javascript function to extract Id from document. Default: null",
"paramType":"TEXT",
"isOptional":true
},
{
"name":"indexFnPath",
"label":"Path to javascript file containing function to extract Index from document",
"helpText":"Path to javascript file containing function to extract Index from document, ex: gs://path/to/indexFn.js. Default: null",
"paramType":"TEXT",
"isOptional":true
},
{
"name":"indexFnName",
"label":"Name of javascript function to extract Index from document",
"helpText":"Name of javascript function to extract Index from document. Default: null. * Will override index provided.",
"paramType":"TEXT",
"isOptional":true
},
{
"name":"typeFnPath",
"label":"Path to javascript file containing function to extract Type from document",
"helpText":"Path to javascript file containing function to extract Type from document, ex: gs://path/to/typeFn.js. Default: null",
"paramType":"TEXT",
"isOptional":true
},
{
"name":"typeFnName",
"label":"Name of javascript function to extract Type from document",
"helpText":"Name of javascript function to extract Type from document. Default: null. * Will override type provided.",
"paramType":"TEXT",
"isOptional":true
},
{
"name":"autoscalingAlgorithm","label":"Autoscaling algorithm to use",
"helpText":"Autoscaling algorithm to use: THROUGHPUT_BASED",
"paramType":"TEXT",
"isOptional":true
},
{
"name":"numWorkers","label":"Number of workers Dataflow will start with",
"helpText":"Number of workers Dataflow will start with",
"paramType":"TEXT",
"isOptional":true
},
{
"name":"maxNumWorkers","label":"Maximum number of workers Dataflow job will use",
"helpText":"Maximum number of workers Dataflow job will use",
"paramType":"TEXT",
"isOptional":true
},
{
"name":"workerMachineType","label":"Worker Machine Type to use in Dataflow Job",
"helpText":"Machine Type to Use: n1-standard-4",
"paramType":"TEXT",
"isOptional":true
}
]},
"sdk_info":{"language":"JAVA"}
}' > image_spec.json
gsutil cp image_spec.json ${TEMPLATE_IMAGE_SPEC}
rm image_spec.json
```
### Testing Template
The template unit tests can be run using:
```sh
mvn test
```
### Executing Template
The template requires the following parameters:
* inputFileSpec: Pattern to where data lives, ex: gs://mybucket/somepath/*.csv
* nodeAddresses: Comma separated list of Elasticsearch nodes to connect to, ex: http://my-node1,http://my-node2
* index: The index toward which the requests will be issued, ex: my-index
* documentType: The document type toward which the requests will be issued, ex: my-document-type
* containsHeaders: Set to true if file(s) contain headers.
* deadletterTable: Deadletter table in BigQuery for failed inserts in form: project-id:dataset.table
* delimiter: Delimiting character in CSV file(s). Default: use delimiter found in csvFormat
The template has the following optional parameters:
* csvFormat: Csv format according to [Apache Commons CSV format](https://commons.apache.org/proper/commons-csv/apidocs/org/apache/commons/csv/CSVFormat.html). Default is: Default
NOTE: Must match format names exactly found [here](http://commons.apache.org/proper/commons-csv/apidocs/org/apache/commons/csv/CSVFormat.Predefined.html#Default)
* jsonSchemaPath: Path to JSON schema, ex gs://path/to/schema. Default: null.
* largeNumFiles: Set to true if number of files is in the tens of thousands. Default: false
* batchSize: Batch size in number of documents. Default: 1000
* batchSizeBytes: Batch size in number of bytes. Default: 5242880 (5mb)
* javascriptTextTransformGcsPath: Gcs path to javascript udf source. Udf will be preferred option for transformation if supplied. Default: null
* javascriptTextTransformFunctionName: UDF Javascript Function Name. Default: null
* maxRetryAttempts: Max retry attempts, must be > 0. Default: no retries
* maxRetryDuration: Max retry duration in milliseconds, must be > 0. Default: no retries
* usePartialUpdates: Set to true to issue partial updates. Default: false
* idFnPath: Path to javascript file containing function to extract Id from document, ex: gs://path/to/idFn.js. Default: null
* idFnName: Name of javascript function to extract Id from document. Default: null
* indexFnPath: Path to javascript file containing function to extract Index from document, ex: gs://path/to/indexFn.js. Default: null
* indexFnName: Name of javascript function to extract Index from document. Default: null
* Will override index provided.
* typeFnPath: Path to javascript file containing function to extract Type from document, ex: gs://path/to/typeFn.js. Default: null
* typeFnName: Name of javascript function to extract Type from document. Default: null
* Will override type provided.
Template can be executed using the following gcloud command:
```sh
export JOB_NAME="${TEMPLATE_MODULE}-`date +%Y%m%d-%H%M%S-%N`"
gcloud beta dataflow flex-template run ${JOB_NAME} \
--project=${PROJECT} --region=us-central1 \
--template-file-gcs-location=${TEMPLATE_IMAGE_SPEC} \
--parameters inputFileSpec=${INPUT_FILE_SPEC},nodeAddresses=${NODE_ADDRESSES},index=${INDEX},documentType=${DOCUMENT_TYPE},containsHeaders=${HEADERS},deadletterTable=${DEADLETTER_TABLE},delimiter=${DELIMITER}
```